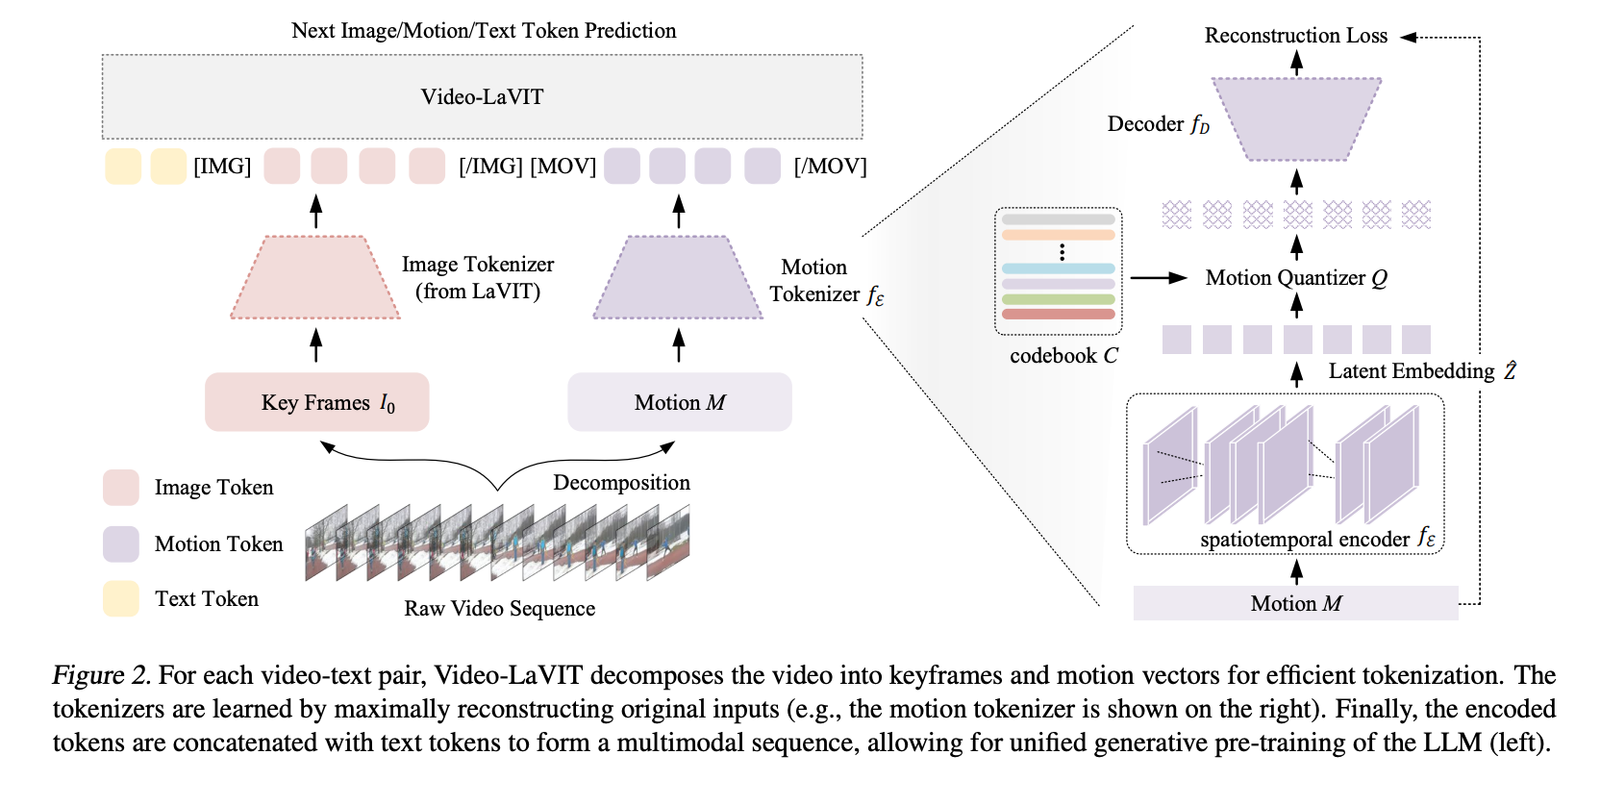
AI News This AI Paper from China Introduces Video-LaVIT: Unified Video-Language Pre-training with Decoupled Visual-Motional Tokenization Feb 26, 20243 min read
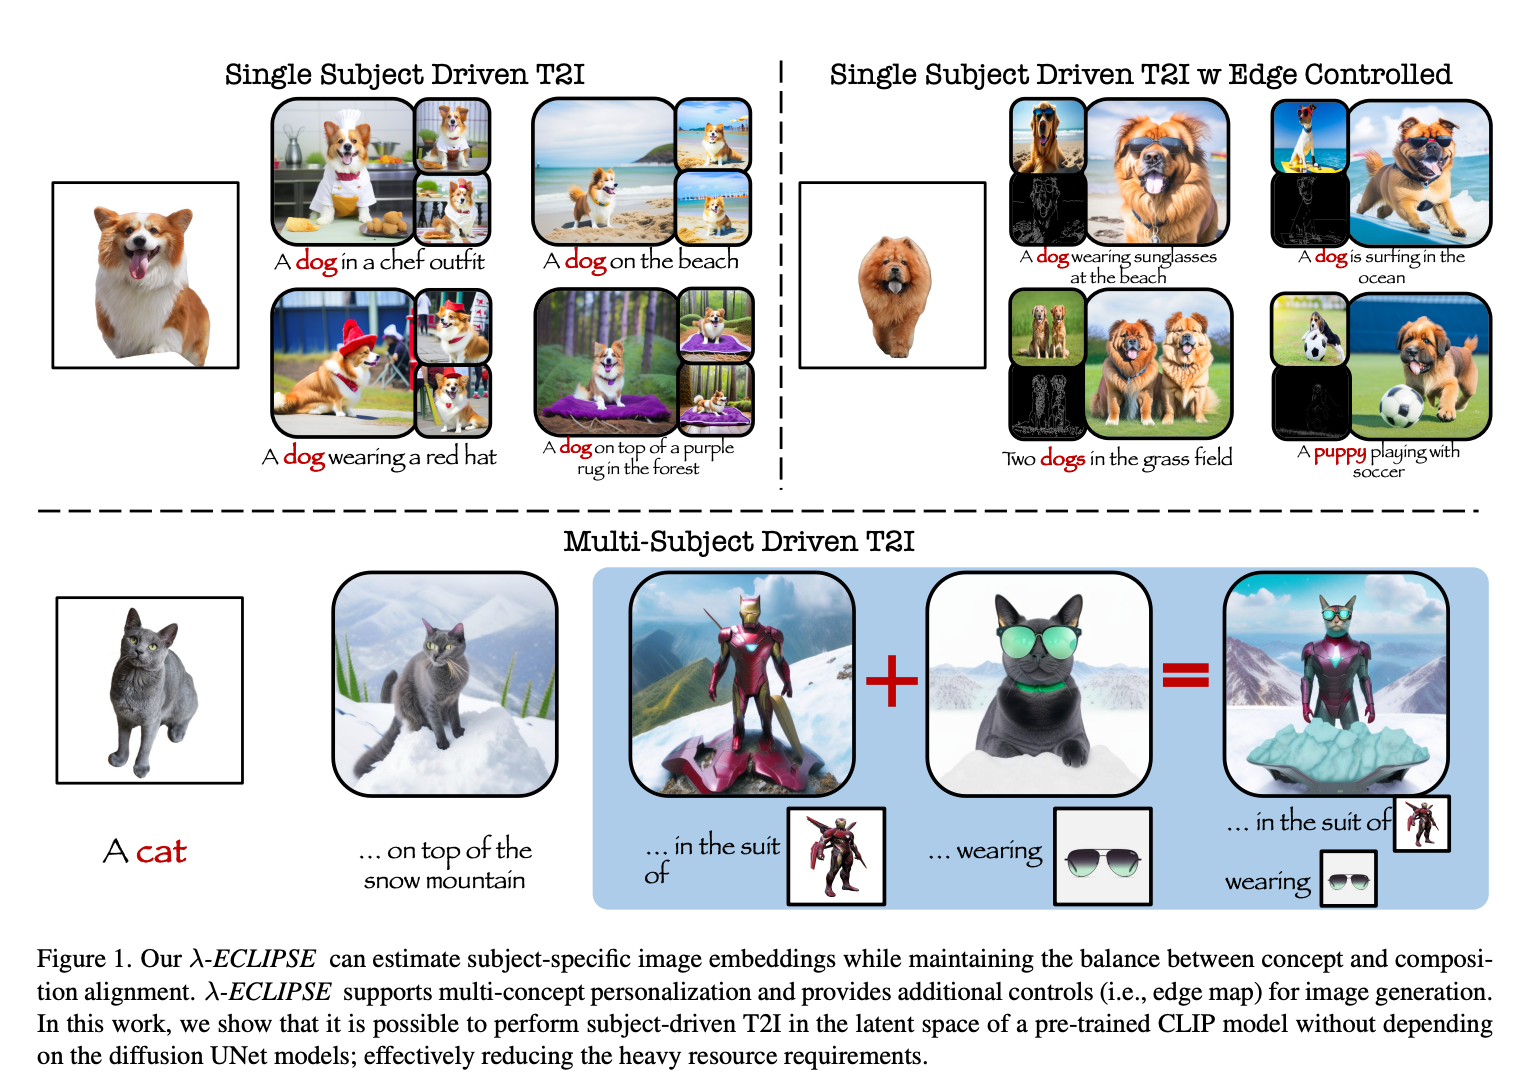
AI News Arizona State University Researchers λ-ECLIPSE: A Novel Diffusion-Free Methodology for Personalized Text-to-Image (T2I) Applications Feb 25, 20243 min read
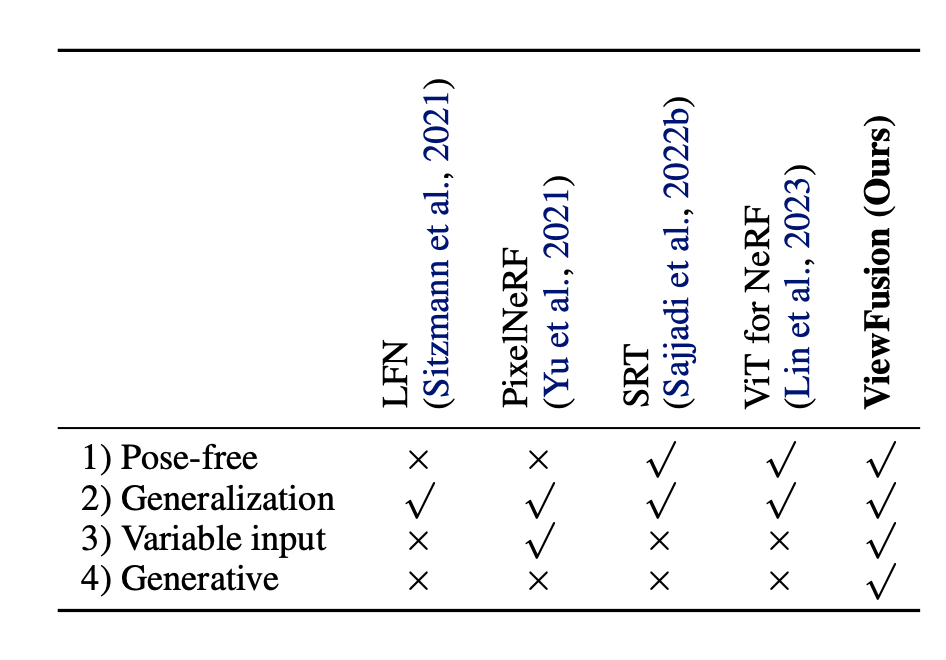
AI News Researchers from Aalto University ViewFusion: Revolutionizing View Synthesis with Adaptive Diffusion Denoising and Pixel-Weighting Techniques Feb 25, 20243 min read
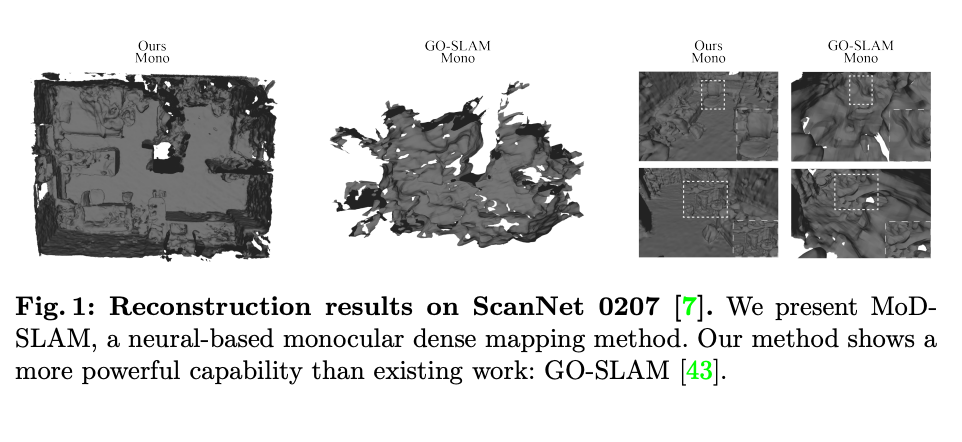
AI News Meet MoD-SLAM: The Future of Monocular Mapping and 3D Reconstruction in Unbounded Scenes Feb 24, 20242 min read
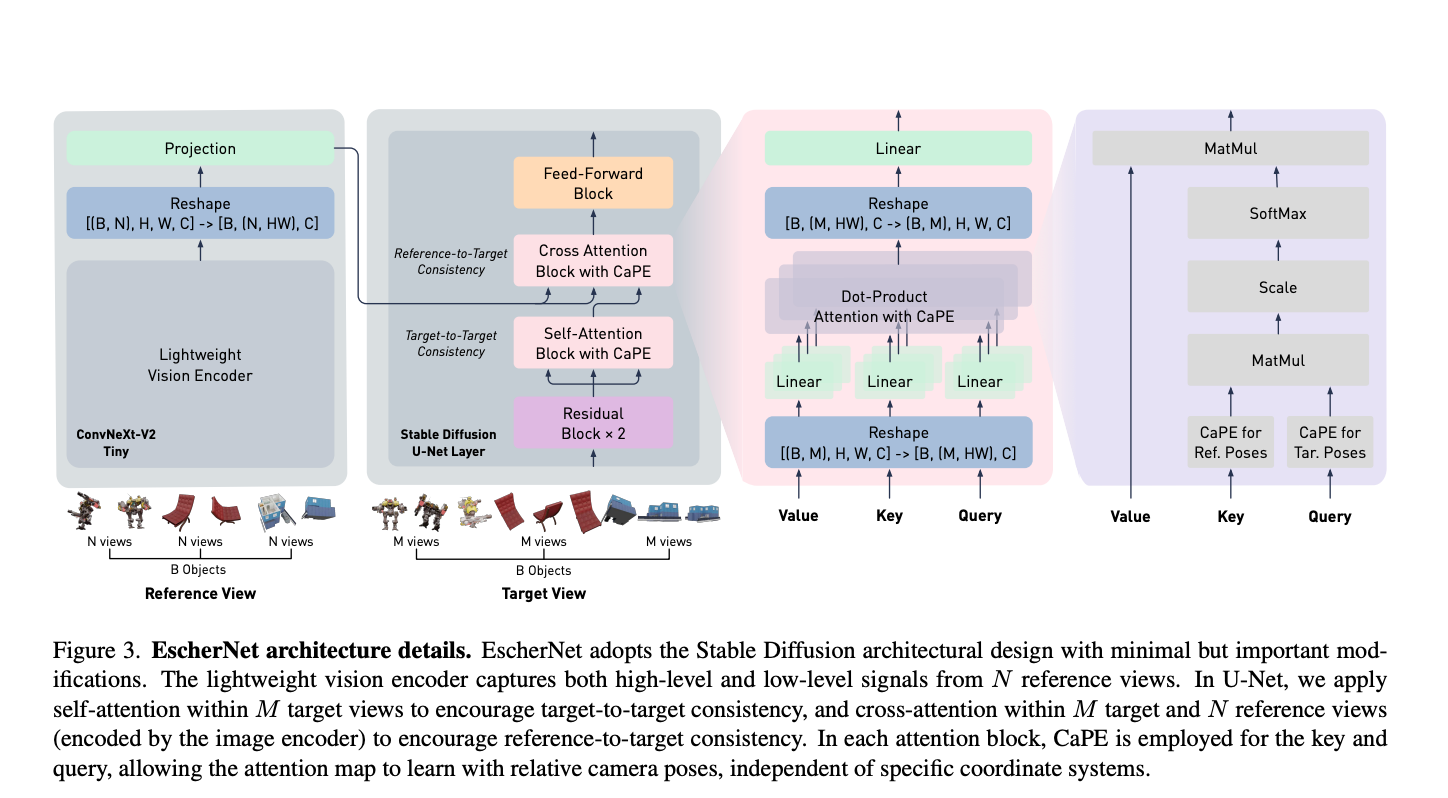
AI News Meet EscherNet: A Multi-View Conditioned Diffusion Model for View Synthesis Feb 24, 20242 min read
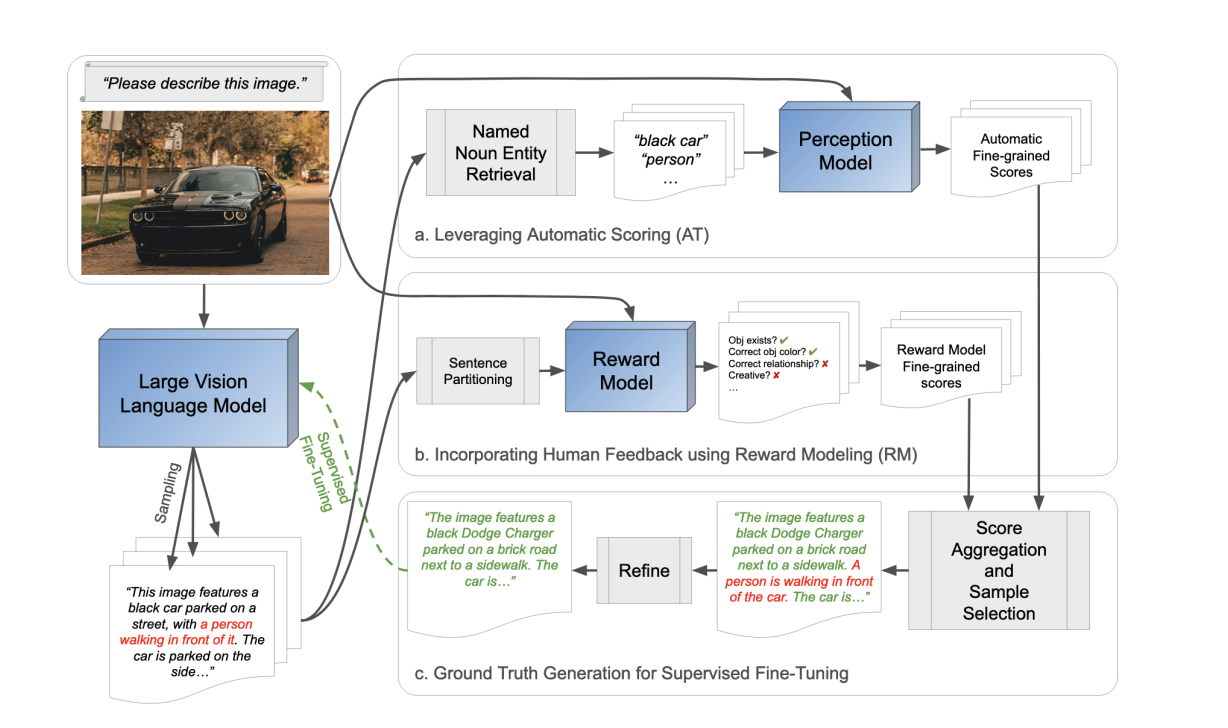
AI News Researchers from UT Austin and AWS AI Introduce a Novel AI Framework ‘ViGoR’ that Utilizes Fine-Grained Reward Modeling to Significantly Enhance the Visual Grounding of LVLMs over Pre-Trained Baselines Feb 23, 20242 min read
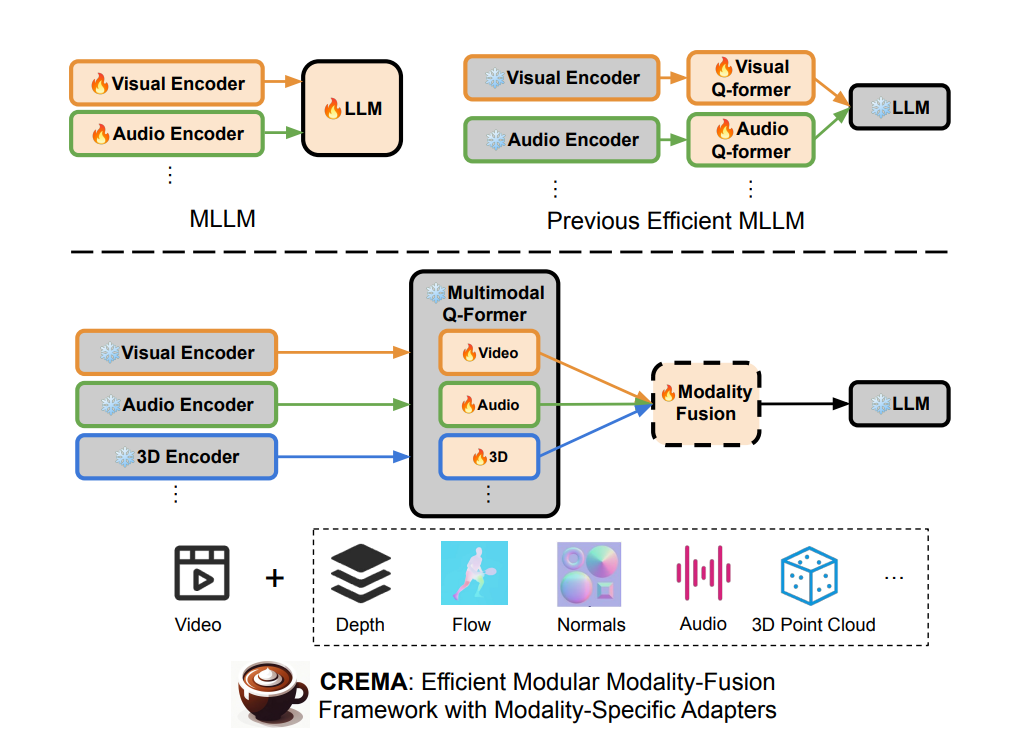
AI News CREMA by UNC-Chapel Hill: A Modular AI Framework for Efficient Multimodal Video Reasoning Feb 23, 20243 min read
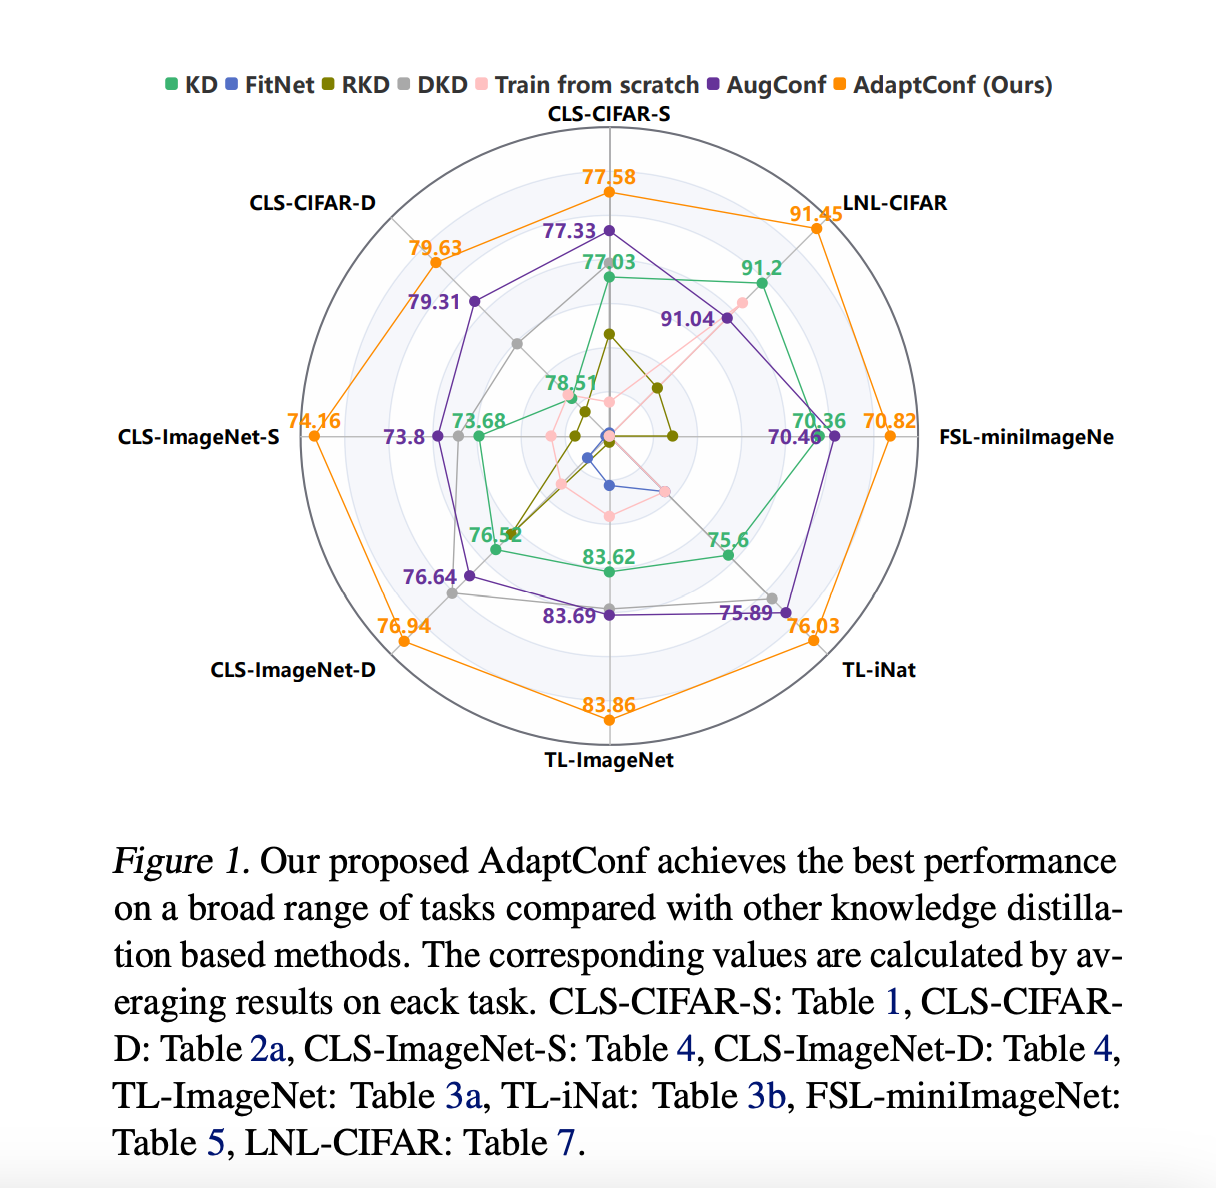
AI News Huawei Researchers Introduce a Novel and Adaptively Adjustable Loss Function for Weak-to-Strong Supervision Feb 22, 20242 min read
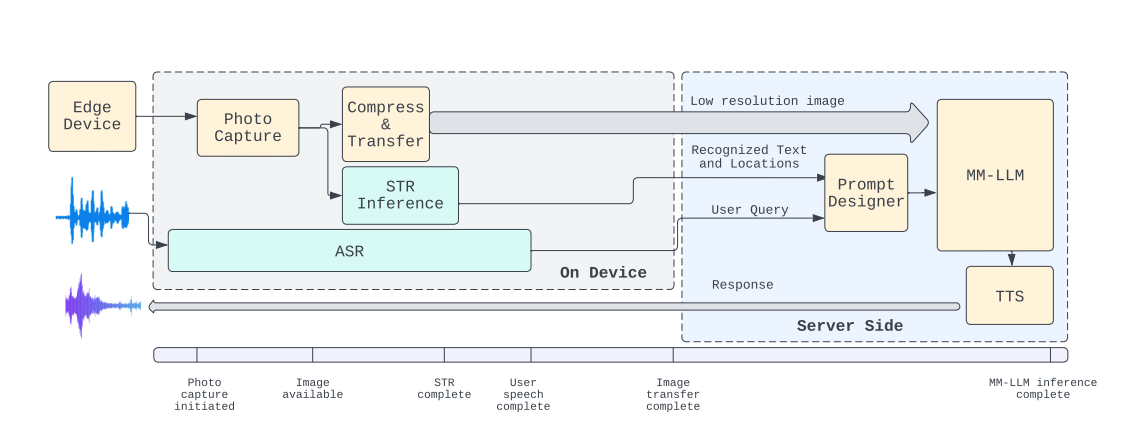
AI News Meta Reality Labs Introduce Lumos: The First End-to-End Multimodal Question-Answering System with Text Understanding Capabilities Feb 22, 20243 min read
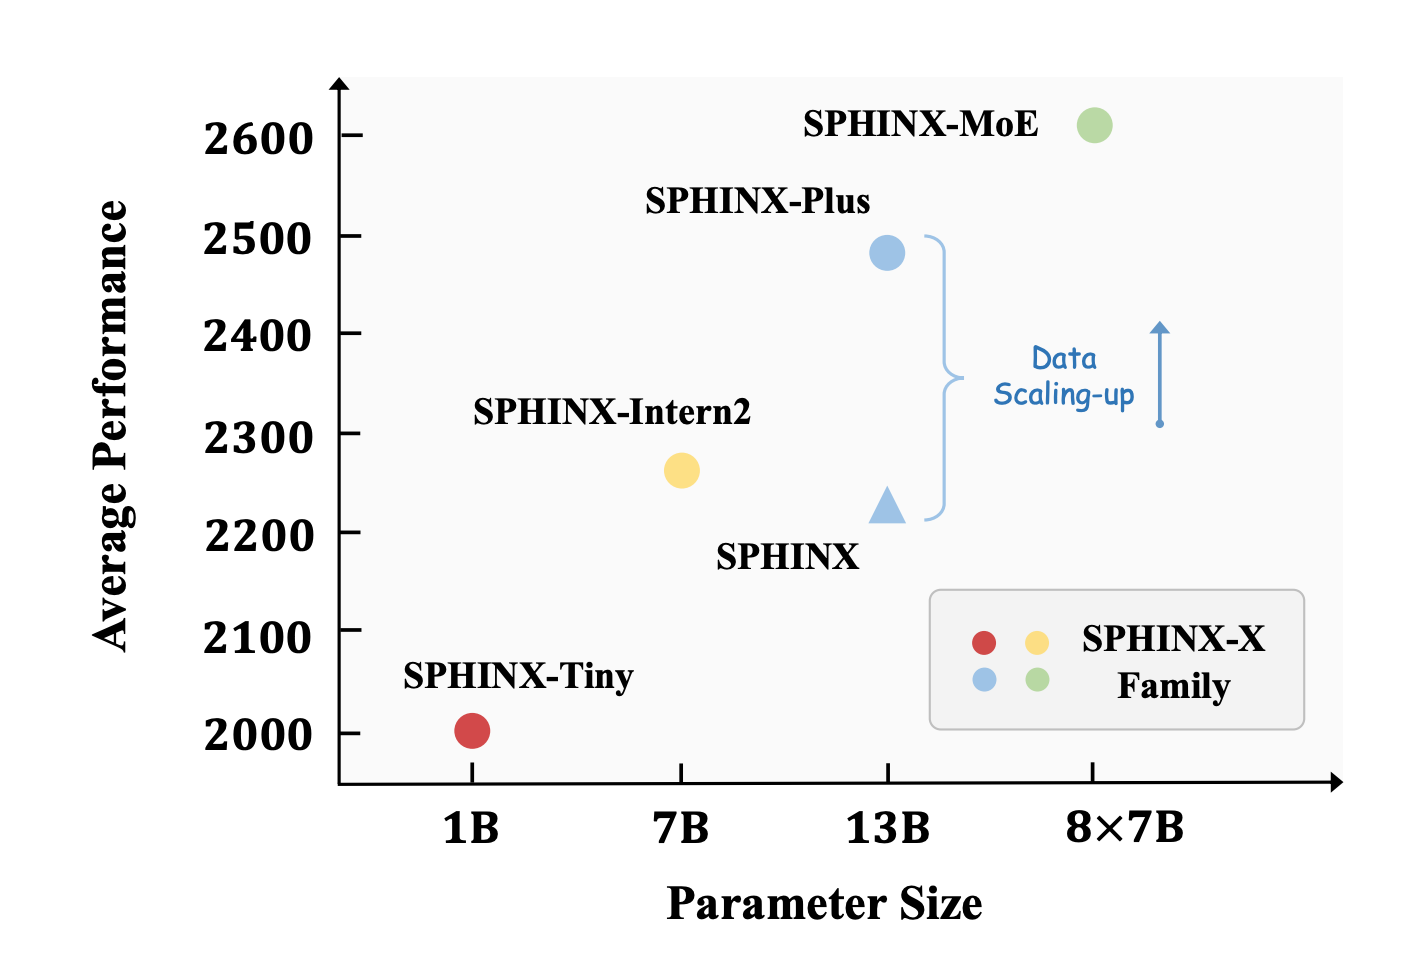
AI News Meet SPHINX-X: An Extensive Multimodality Large Language Model (MLLM) Series Developed Upon SPHINX Feb 21, 20243 min read
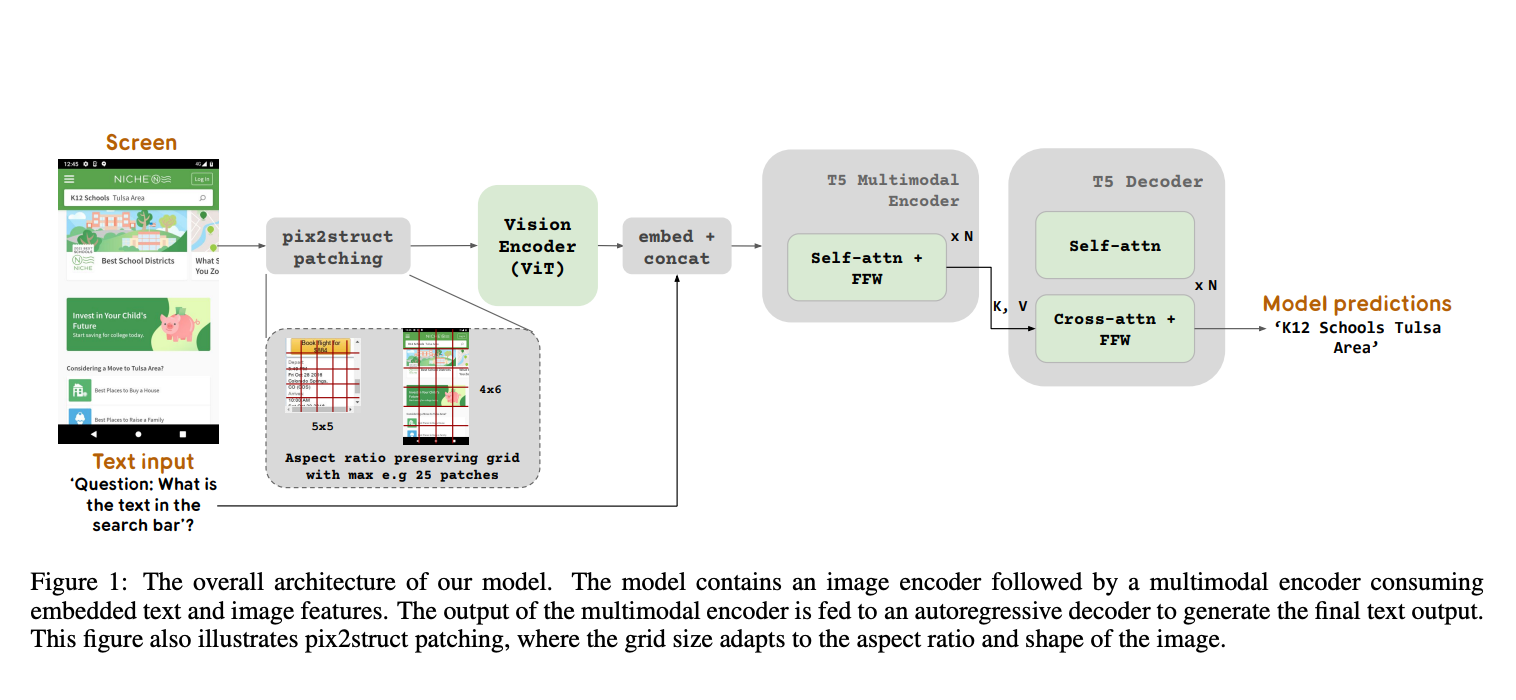
AI News Google AI Introduces ScreenAI: A Vision-Language Model for User interfaces (UI) and Infographics Understanding Feb 21, 20243 min read
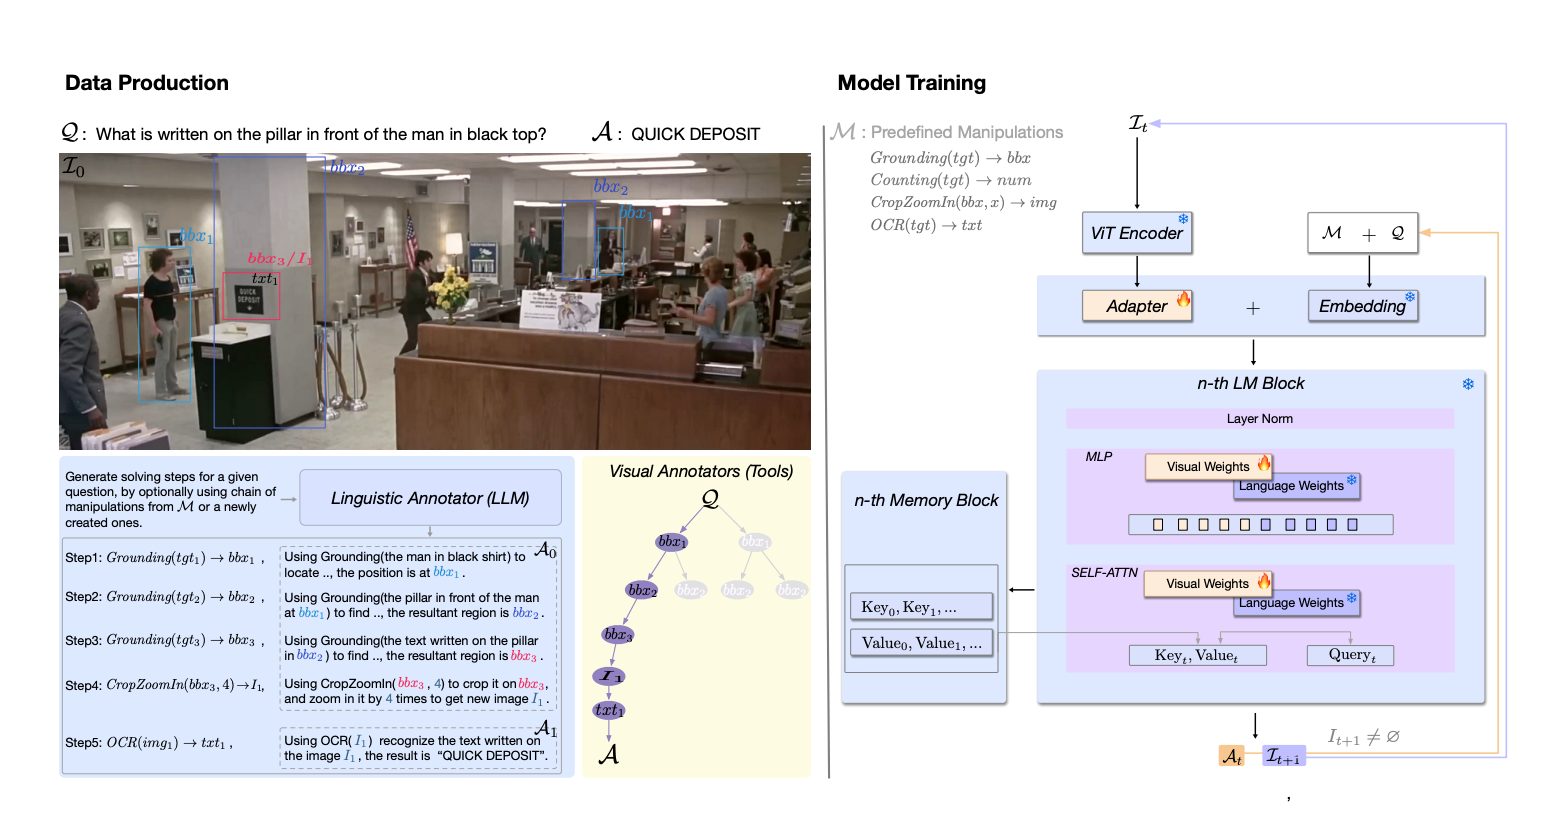
AI News Enhancing Vision-Language Models with Chain of Manipulations: A Leap Towards Faithful Visual Reasoning and Error Traceability Feb 17, 20243 min read