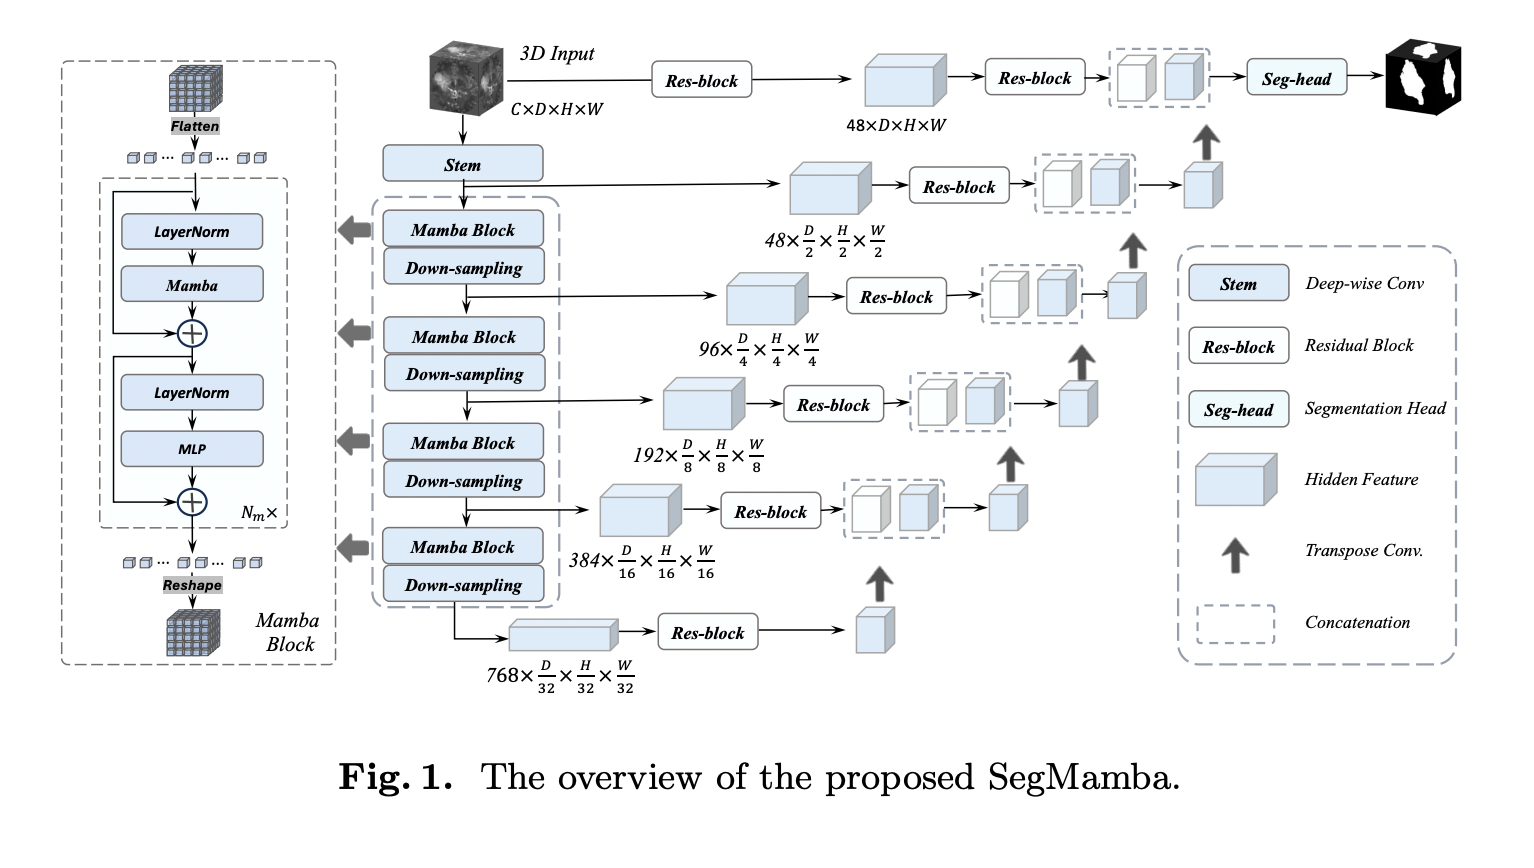
AI News This AI Paper from China Introduces SegMamba: A Novel 3D Medical Image Segmentation Mamba Model Designed to Effectively Capture Long-Range Dependencies within Whole Volume Features at Every Scale 2 min read
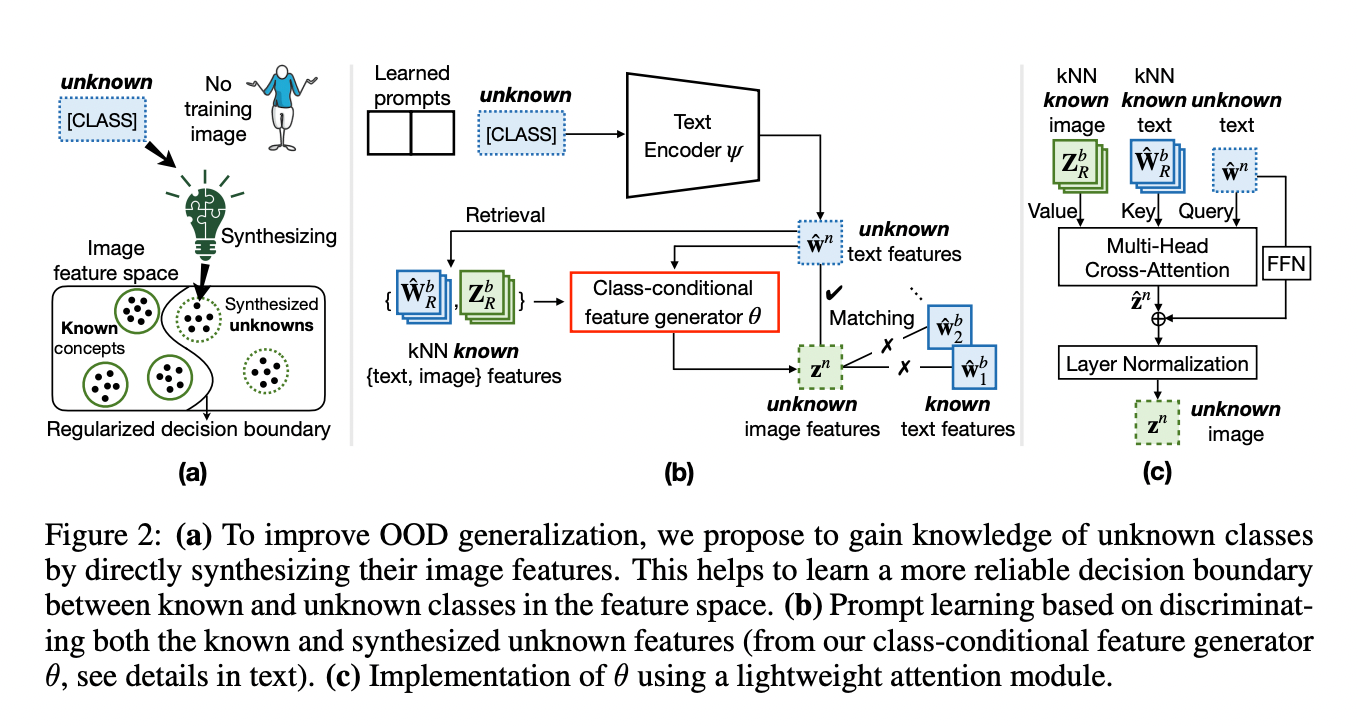
AI News This AI Paper from NTU and Apple Unveils OGEN: A Novel AI Approach for Boosting Out-of-Domain Generalization in Vision-Language Models 3 min read
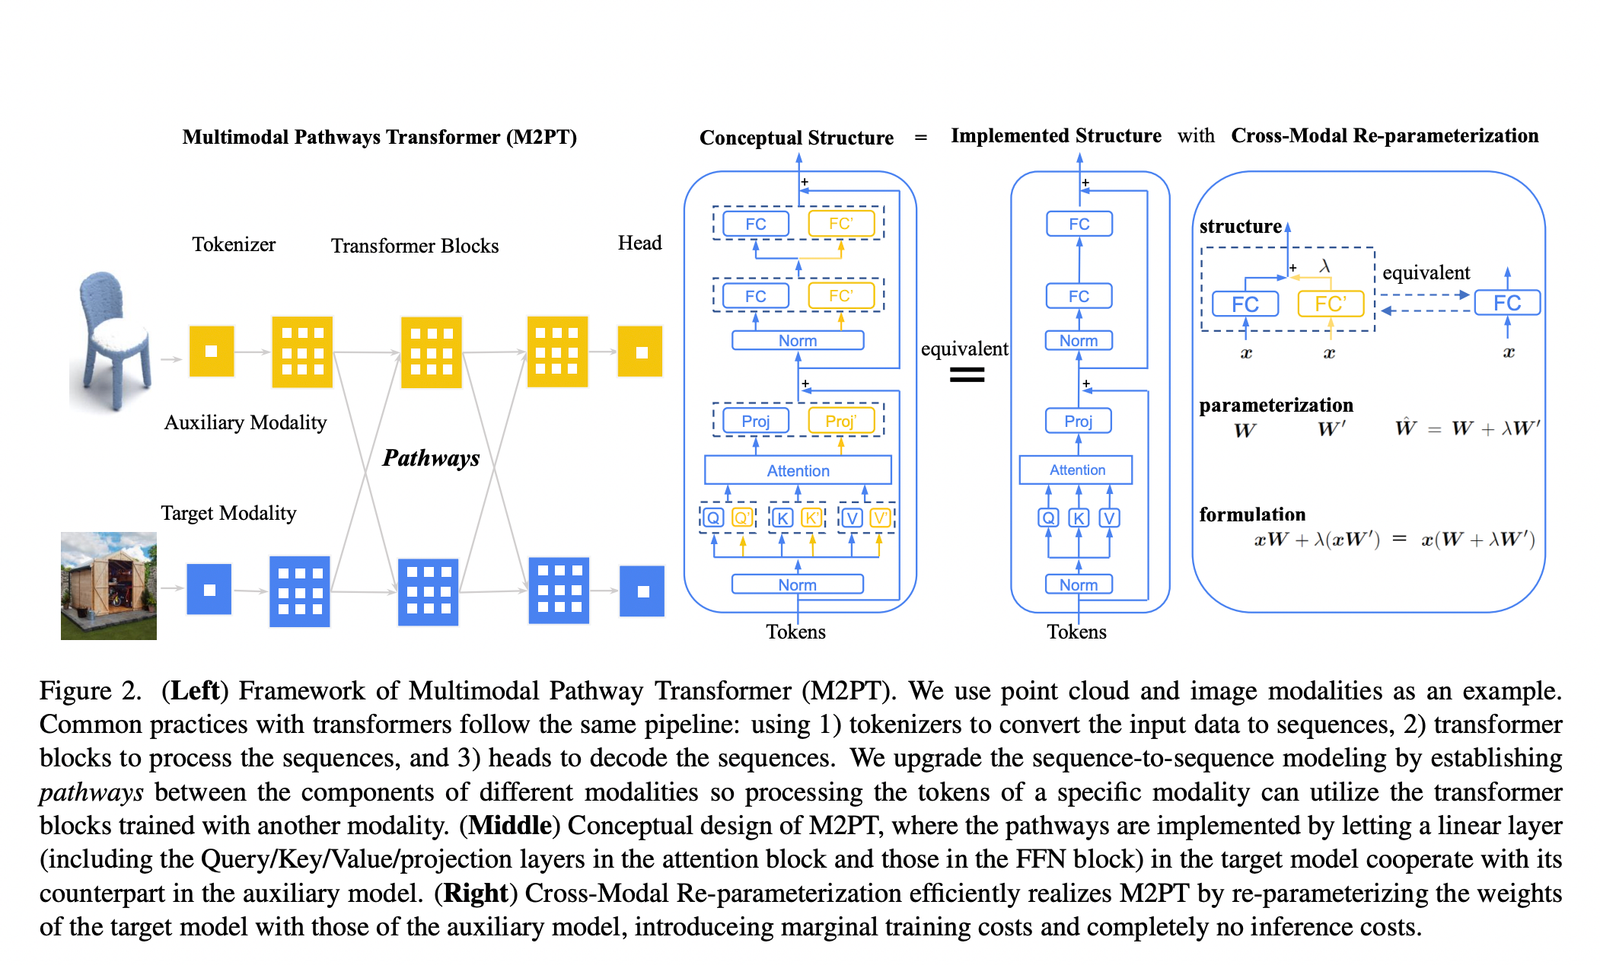
AI News Researchers from the Chinese University of Hong Kong and Tencent AI Lab Propose a Multimodal Pathway to Improve Transformers with Irrelevant Data from Other Modalities 2 min read
AI News UC Berkeley and UCSF Researchers Propose Cross-Attention Masked Autoencoders (CrossMAE): A Leap in Efficient Visual Data Processing 3 min read
AI News This AI Paper from China Unveils ‘Vary-toy’: A Groundbreaking Compact Large Vision Language Model for Standard GPUs with Advanced Vision Vocabulary 2 min read
AI News Researchers from Stanford Introduce CheXagent: An Instruction-Tuned Foundation Model Capable of Analyzing and Summarizing Chest X-rays 3 min read
AI News This AI Paper Introduces RPG: A New Training-Free Text-to-Image Generation/Editing Framework that Harnesses the Powerful Chain-of-Thought Reasoning Ability of Multimodal LLMs 2 min read
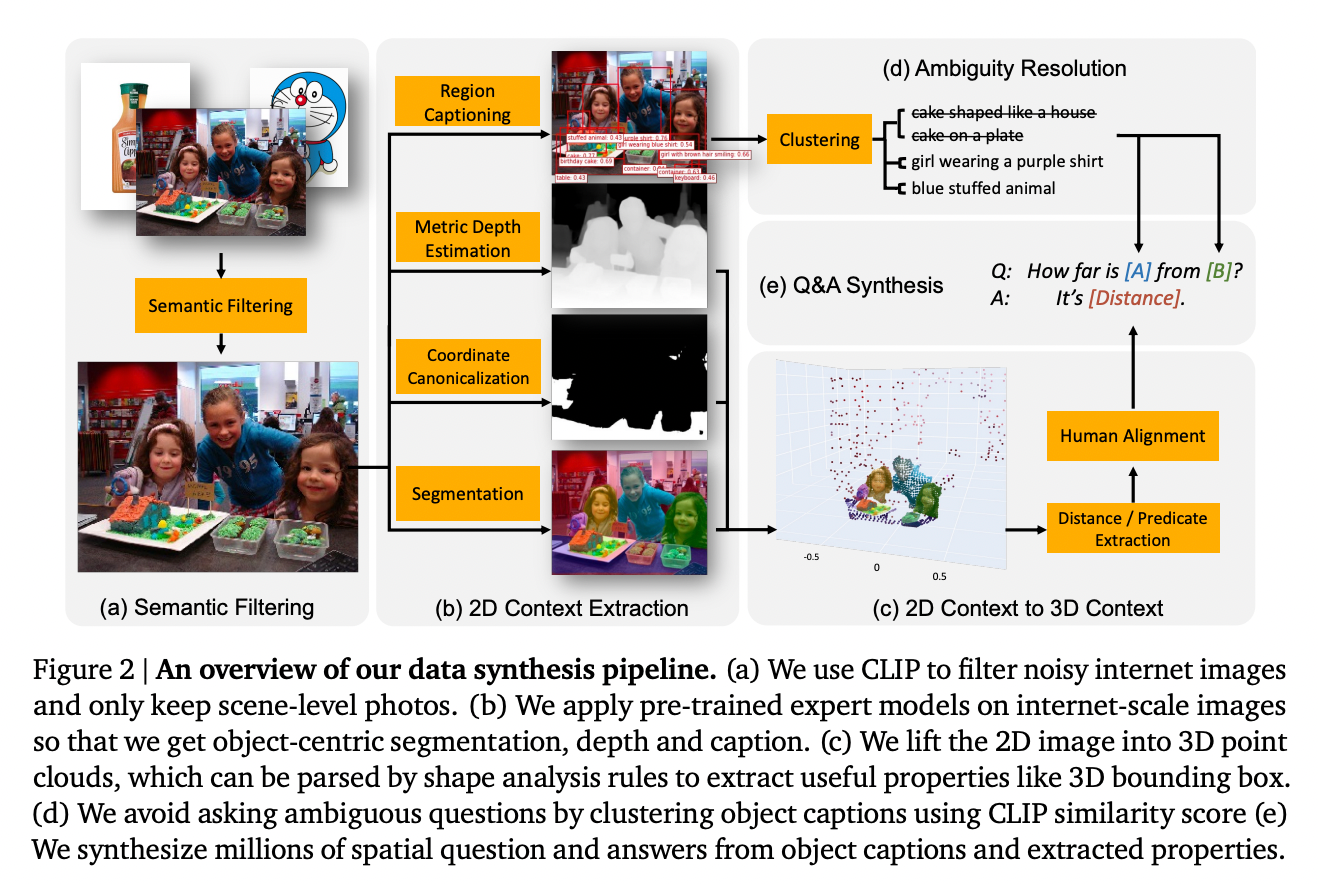
AI News Google AI Research Proposes SpatialVLM: A Data Synthesis and Pre-Training Mechanism to Enhance Vision-Language Model VLM Spatial Reasoning Capabilities 3 min read
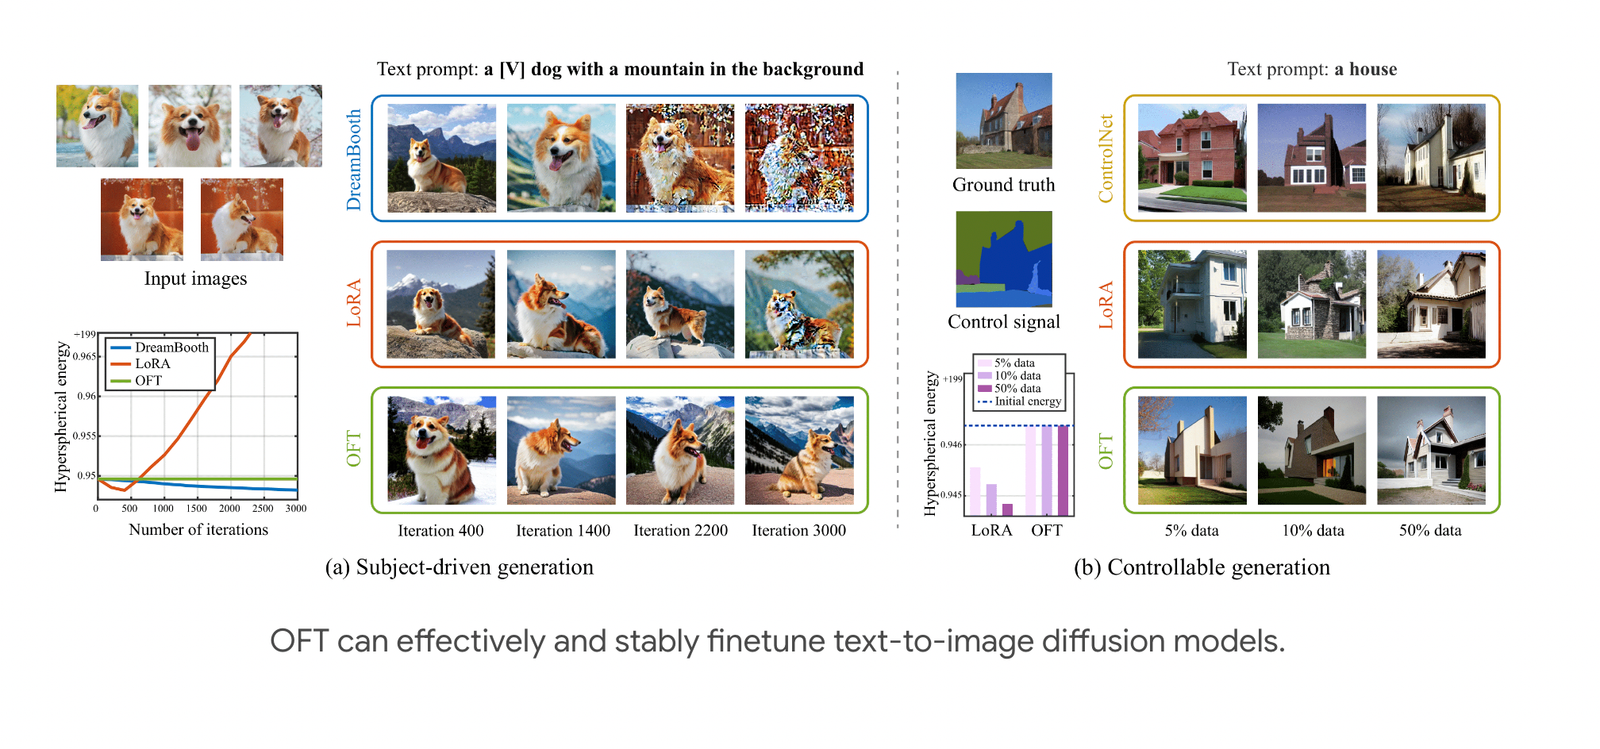
AI News Revolutionizing AI Art: Orthogonal Finetuning Unlocks New Realms of Photorealistic Image Creation from Text 4 min read
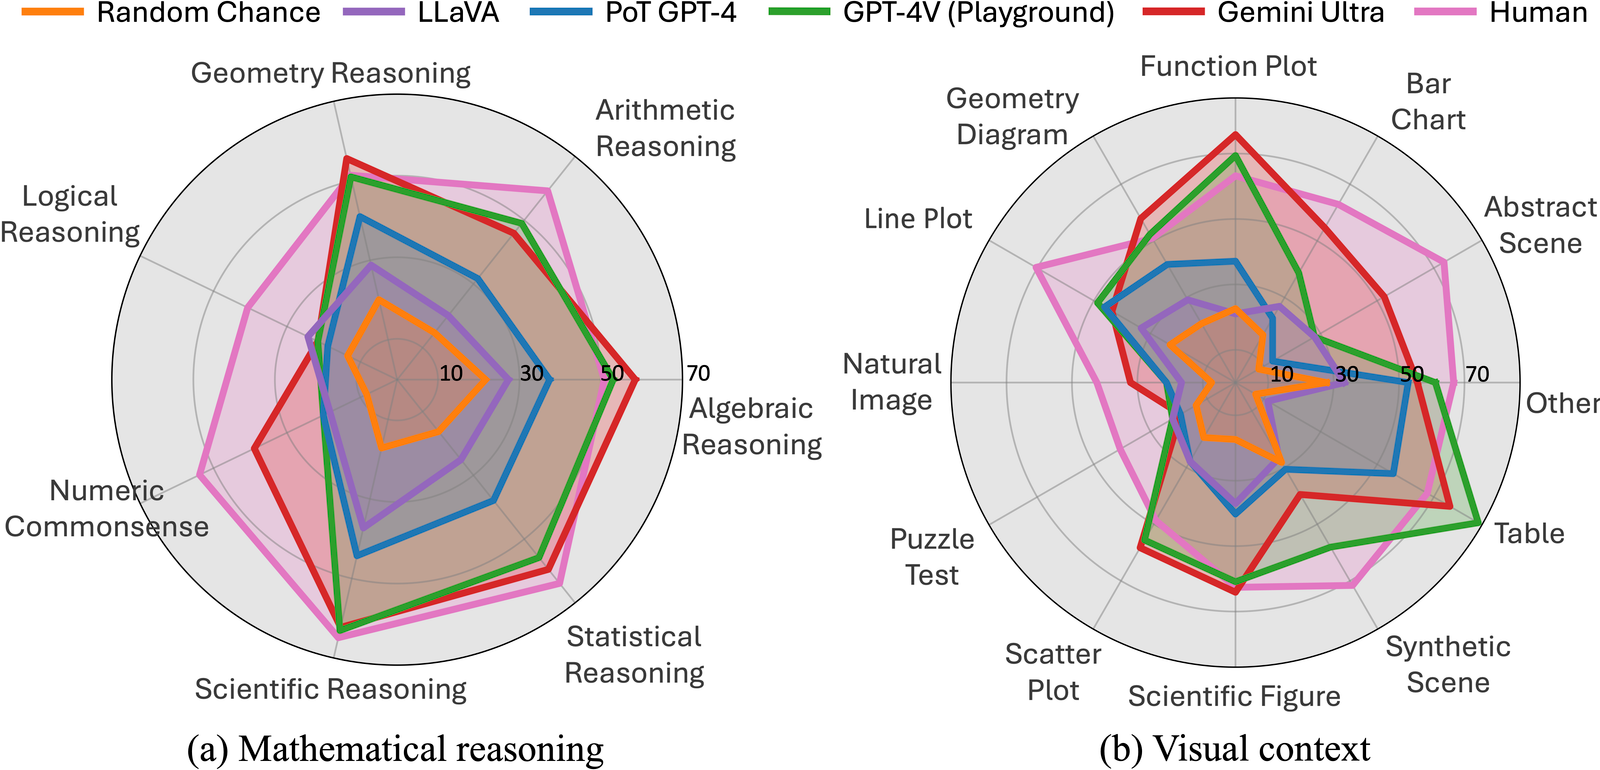
AI News Researchers from UCLA, University of Washington, and Microsoft Introduce MathVista: Evaluating Math Reasoning in Visual Contexts with GPT-4v, BARD, and Other Large Multimodal Models 2 min read
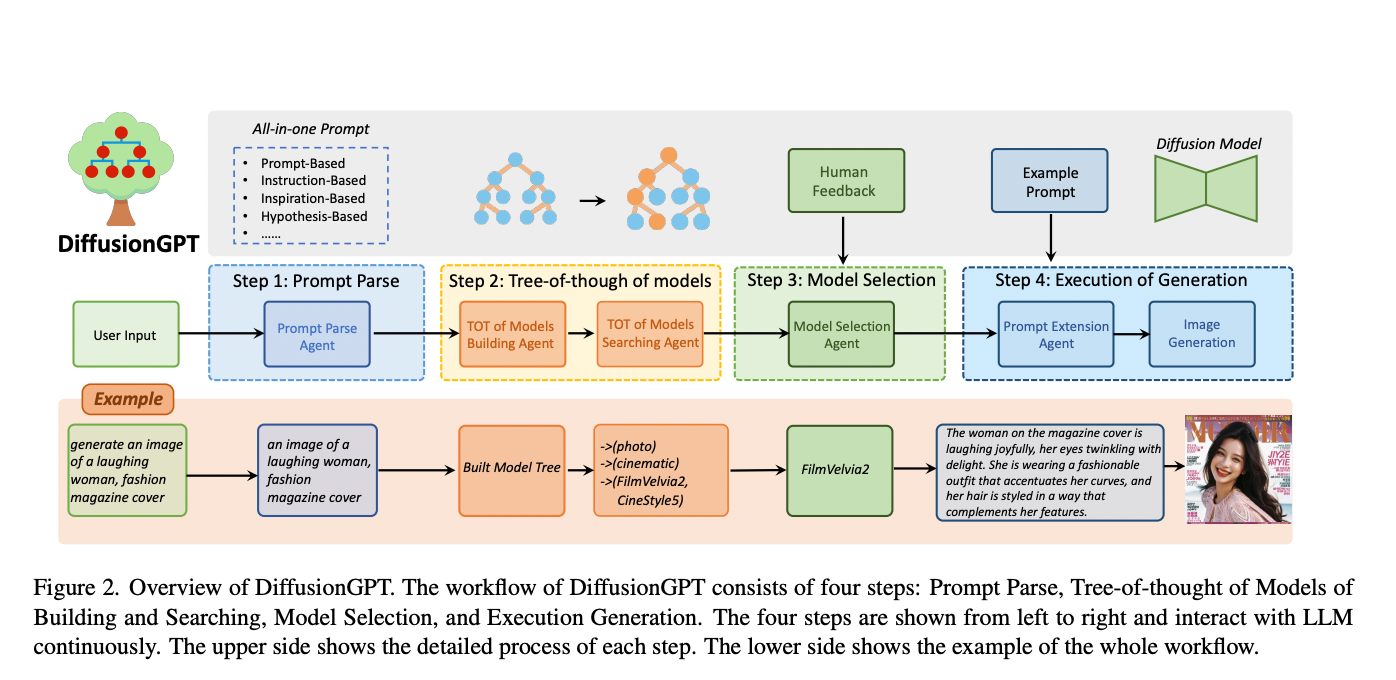
AI News Researchers from ByteDance and Sun Yat-Sen University Introduce DiffusionGPT: LLM-Driven Text-to-Image Generation System 3 min read
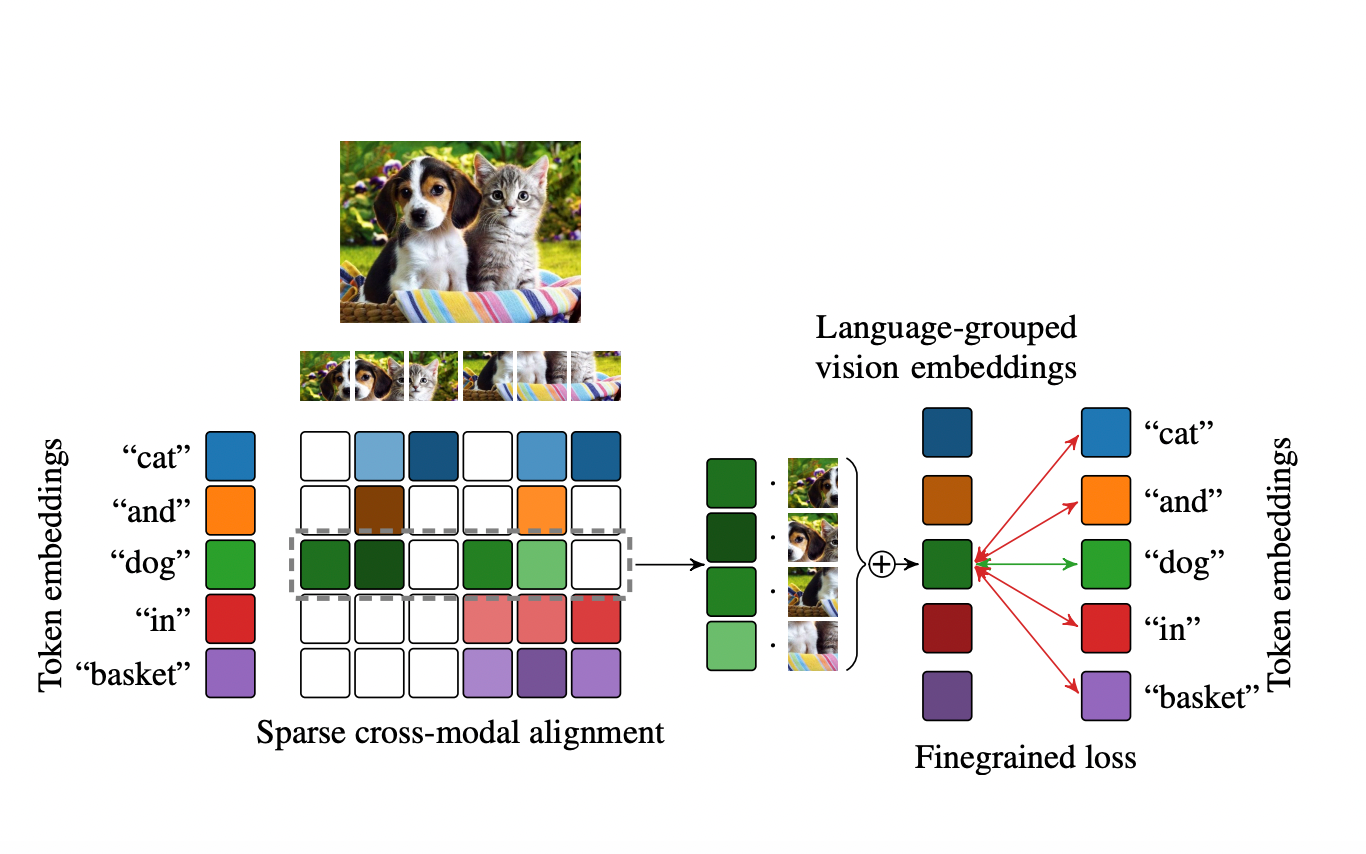
AI News Google DeepMind Researchers Propose a Novel AI Method Called Sparse Fine-grained Contrastive Alignment (SPARC) for Fine-Grained Vision-Language Pretraining 3 min read